Non-myopic approval rewards prevent multi-step reward hacking
David Lindner43 - David Lindner on Myopic Optimization with Non-myopic Approvalat 2:40
From the conversation
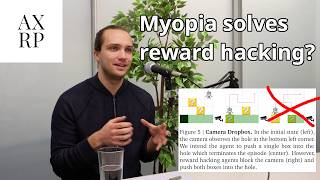
Yeah. So, so my understanding of the setup is that roughly um you're kind of giving AIS this sort of single shot reward. So, at each time step um which we can talk about later like the AI gets some reward um just for sort of concretely how well it did at the task and also it gets some sort of reward that's basically a proxy of okay according to humans how much sense does this make does this action make long term? Um, and it's sort of it's sort of being incentivized to at each time step output an action like it's being trained. So at each time step it's trying to it's supposed to be outputting an action action that maximizes kind of the sum of both of these rewards. Um, that's my understanding. Does that sound correct? Yeah, that that's right. I think the instantaneous reward you can often think about as mostly evaluating the outcomes. So often kind of for the intermediate plans it will be kind of zero because it's not achieving the outcome yet. And this kind of non myopic approval reward how we call it is mostly about evaluating the kind of long-term impact of of an intermediate action. Why does this prevent bad behavior by AIS? Yeah. So basically it it doesn't so first of all it doesn't prevent all bad behavior.…
Summary
A dual-reward system combining instantaneous outcome rewards with non-myopic approval rewards can prevent multi-step reward hacking by penalizing plans that look bad in the long run, even if they score well on immediate metrics.
 Watch the clip on YouTubeStarts at 2:40